
AI Dev Reads
AI engineering posts picked from company and developer tech blogs such as Toss, LINE, Anthropic and OpenAI, each with a short summary. Tap to read the original.
Last searched Oct 19, 7:44 PM KST
Zero's BlogAdded Oct 19
What exactly is RAG?
Using a shopping-mall support bot as the example, it explains RAG, fetching only the relevant chunks for each question, with a LangChain code walkthrough. Citing Anthropic's Contextual Retrieval, it notes retrieval failures fell 35% with chunk context, 49% with keyword search added and 67% with reranking, and suggests just putting everything in the prompt when docs are under 200K tokens.
AgentsModels & evals
Does Claude really remember your name? LLMs and context
Each API call is independent, so the model remembers nothing between calls; chat apps just resend the whole conversation, which makes it look like memory. Send "my name is Youngsu" along and it uses the name; drop it and it says you never told it. The same applies to Claude Code's CLAUDE.md and memory files, which only help once they're loaded into context.
Models & evalsAgents
What exactly are LangChain and LangGraph?
LangChain supplies the parts (model wiring, prompts, tools, RAG), while LangGraph is an execution engine that controls flow with state, nodes and edges. They sit at different layers rather than replacing each other. Use the model API directly for single calls, LangChain for tool-using agents, and LangGraph when you need human approval, branching or pause-and-resume.
Agents
Hugging FaceAdded Oct 19
Welcome Beam: a 501B open model you can own, customize, and scale
Reflection released Beam under Apache 2.0: a 501B-parameter sparse MoE with 23B active per token and a 1M-token context, reporting 81.6% on SWE-bench Verified and 80.1% on Terminal Bench. It runs day-0 in transformers, vLLM and SGLang.
Models & evals
LY CorporationAdded Oct 19
Automating E2E regression tests with AI: turning one-click into a pipeline (LY Corp)
AI-generated E2E tests ran but checked the wrong things, so the team added spec tracing, gap questions, pre-run checks, deliberately wrong expectations to catch false positives, and human review packets. All 98 manual regression tests moved to Playwright, and coverage grew to 196.
Coding toolsCase studies
뱅크샐러드Added Oct 19
Why DDD matters more in the age of AI coding (Banksalad)
The more code AI writes, the more the structure around it matters. Banksalad split a Go credit service into business-level bounded contexts and four layers, and says coding agents now read several times less code per change and reviews stay narrower.
Coding toolsCase studies
LangChainAdded Oct 19
The Most Common Questions About Agent Evals, Answered
Where to start with agent evals: offline vs online evals, evaluator types and LLM judges, benchmarks, multi-turn evals, and how to keep the cost down.
AgentsModels & evals
Anthropic EngineeringAdded Oct 19
Redesigning source control for always-on agents (Anthropic)
As daily merges grew from about 2,500 in May to over 30,000 by September, Anthropic replaced git for its monorepo with Scion, an in-house system that keeps commits, merges and history on the server and fetches only needed files. It uses about 200x less CPU and memory than the old git mirrors and checkouts dropped from minutes to seconds. Anthropic says it isn't a general-purpose git replacement.
Infra & servingAgents
토스 테크Added Oct 19
Building an AI platform so service teams can focus on product (Toss)
Toss's AI platform team pulled model integration, permissions, usage tracking and incident response out of individual service teams into one platform: a request portal, a model gateway, an MCP gateway for internal tools, input guardrails, Langfuse tracing and a CLI, applied by data tier (L1–L4) and SLA tier.
Infra & servingCase studies
Open SWE: An Open-Source Framework for Internal Coding Agents
Built on Deep Agents and LangGraph, Open SWE gives teams the core building blocks for an internal coding agent, so they don't have to start from scratch to wire one into their own repos and tools.
Coding toolsAgents
GitHub BlogAdded Oct 19
GitHub's model for secret detection: Finding more secrets with less noise
GitHub's context-aware classifier for leaked secrets in code raised weighted acceptance by 11.5% and cut median scan time by 86%, according to the post.
SecurityModels & evals
Run fast, private agents on-device with LFM2.5-24B-A2B
Liquid AI's 24B-parameter reasoning model activates only 2B parameters per token, so it runs fast on your own hardware: 184 tokens/s on an Apple M5 Max and 114 tokens/s on a Ryzen AI Max+ 395. The open weights are on Hugging Face.
Models & evalsAgents
Latent SpaceAdded Oct 19
How Anthropic's Dynamic Workflows Coordinate Claude Agents
A write-up of Anthropic's AI Engineer New York talk. It borrows lessons from Unix and Linux to show how agents can split up bigger projects without overwhelming the developers who oversee them. The talk video is included.
Agents
Squeezing every CPU cycle and building a Milvus sizing rule (Toss)
Toss Securities' data infra team tuned Milvus for vector search: HNSW_SQ8 hit 316 QPS at recall@10 0.954 while cutting per-replica memory from about 335GB to 114GB, and pinning CPU and memory to the same NUMA node added 41% more QPS. They turned the measurements into a rule for how many servers to provision.
Infra & servingCase studies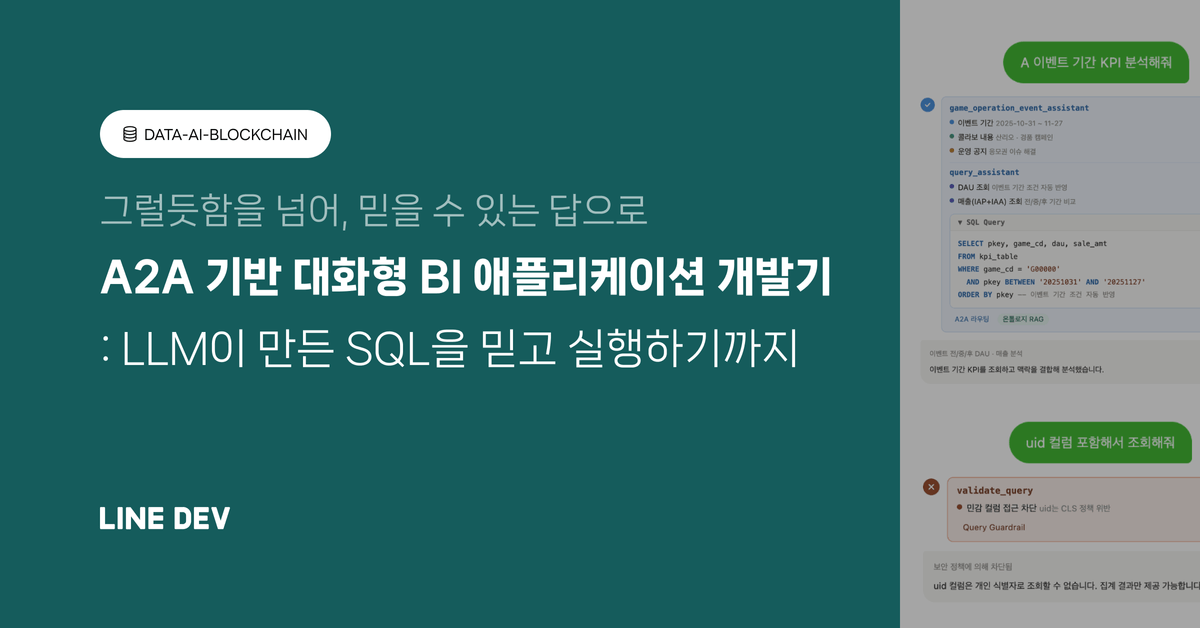
Trusting LLM-written SQL enough to run it: building an A2A conversational BI app (LY Corp)
LY's game platform team built a chat BI app that goes from question to SQL to chart, with A2A agents splitting the roles. To trust generated SQL they added ontology-based RAG for metric definitions, a separate pre-execution guardrail for row- and column-level permissions, and feedback that explains violations.
AgentsSecurity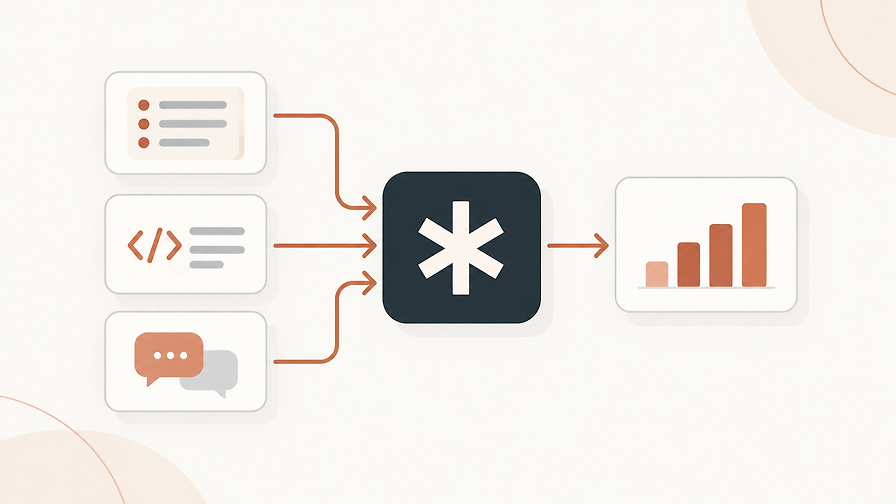
카카오 테크Added Oct 19
Context design lessons from building a data-analysis agent (Kakao)
Kakao's agent finds the right data, writes and runs SQL, and explains the result. The post breaks context into system prompt, tool specs and message history, and shows with example prompts how, as models improved, step-by-step workflow rules moved out of the system prompt and into per-tool usage conditions.
AgentsCase studies- 네이버 D2
네이버 D2Added Oct 19
Agents from first principles: workflows, harnesses, context/memory, MCP/A2A (NAVER D2)
A popular NAVER internal tech meetup talk (video). It untangles terms teams use differently, such as workflow, harness, context vs memory, and MCP vs A2A, by going back to the Anthropic and OpenAI write-ups and the protocol specs.
Agents 
CursorAdded Oct 19
Rollouts and Security Reviewer (Cursor)
Rollouts tracks a change from PR to production, writing a monitoring plan before merge and comparing post-deploy telemetry to the baseline. Security Reviewer checks every PR against the whole codebase with explanations and fixes; Cursor says it cut average review time from 4.8 to 3.8 minutes and raised acceptance to 60–70%.
Coding toolsSecurity
Improved token efficiency (Cursor)
Cursor reworked its agent harness to cut token costs 7% without hurting quality: about 66% less system prompt, rarely used built-in tools loaded on demand (60% fewer static tool-description tokens), and explicit prompt-cache breakpoints (20% fewer cold cache misses).
Coding tools
An AI support service that saved 300 hours a year (Toss Bank)
Toss Bank's jeonse-loan team built an AI assistant that answers questions in users' own words. Support calls fell by 550 a month, about 300 hours a year, and users who got an answer from AI were about 10 percentage points less likely to call. Surfacing common questions at each step raised AI usage up to roughly 5x.
Case studies
우아한형제들Added Oct 19
Rebuilding Baemin's e-contract screens: what we gave to AI and what humans kept (Woowa Brothers)
Most of the code for Baemin's new e-contract screens was written with Claude Code. AI handled view components and draft specs and tests; humans owned boundaries, lint rules and spec approval. It shipped about twice as fast with roughly 8.5x more test code per line, though four bugs surfaced in the first two weeks.
Coding toolsCase studies
How much to hand to the LLM: automating ad analytics reports with AI agents (LY Corp)
LINE Ads' data team automated a daily revenue-change report sent to Slack and email. Code handles calculations, candidate selection and consistency checks; the LLM interprets verified facts into prose; and a tool-calling agent explores causes only within allowed analysis dimensions.
AgentsCase studies
Is the leaderboard's #1 LLM also #1 at Toss? Building Toss Benchmark
Public leaderboards don't guarantee real-world performance, so Toss built a benchmark covering general Korean ability plus its own domain: real operating tasks, policy compliance (Toss IFBench) and commerce knowledge (Toss Knowledge). gemma-4-26B, first on the English math set, fell from 81.74 to 72.43 on the Korean translation and dropped to second.
Models & evalsCase studies